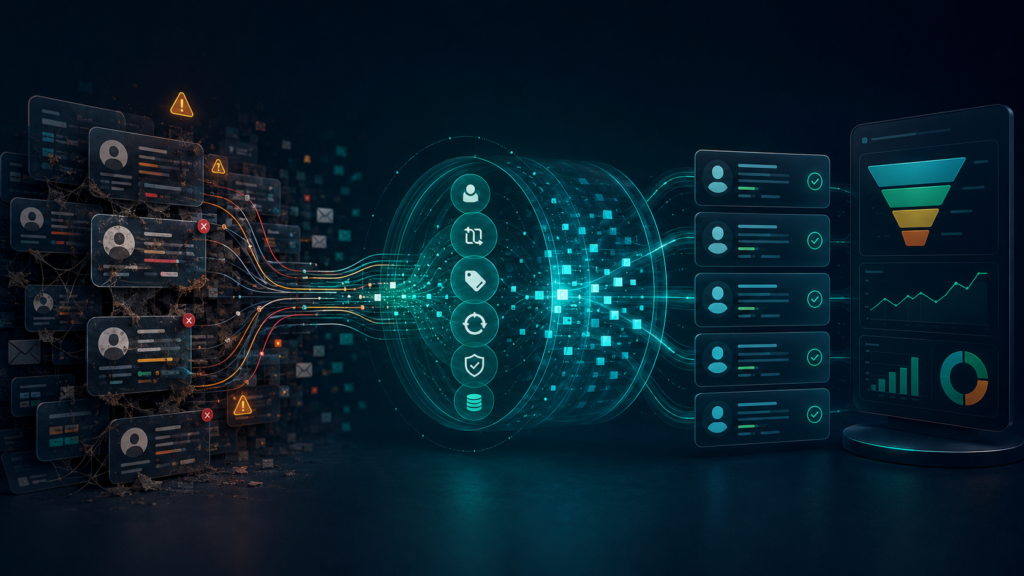
Bad CRM data doesn’t just look untidy. It inflates your pipeline, sends leads to the wrong people and quietly costs revenue. Five practices stop that: retiring old data responsibly, cleaning and standardising records, enriching data continuously, defining what “good data” means for your company, and recalibrating lead scoring. Mature programmes then check that the actions the data triggered actually happened. (For the definition and a weekly-to-quarterly routine, see my guide to the CRM hygiene routine.)
Your CRM may show a healthy pipeline, but how much of it is genuinely active?
In a recent discussion on Reddit’s CRM community, one practitioner reported that approximately 20–25% of the “active” pipeline reviewed across a handful of real-estate CRM audits had no logged activity for more than 30 days. The same audits uncovered inconsistent tags and missing consent information.
This is an anecdotal observation, not an industry-wide benchmark. However, it highlights a familiar problem: a CRM can appear complete while the data inside it is outdated, inconsistent or unusable.
The consequences extend beyond untidy records. Poor CRM hygiene affects sales productivity, forecasting, campaign performance, customer experience and regulatory compliance. It becomes even more dangerous when automated workflows and AI systems act on unreliable data.
Keeping CRM data clean must therefore be treated as an ongoing business discipline, not an annual cleanup exercise.
Key Takeaways
- A full-looking CRM can still be stale: one practitioner’s real-estate CRM audits found roughly 20–25% of “active” pipeline had no logged activity in over 30 days. That is anecdotal, but the pattern is familiar.
- Old data needs a lifecycle, not a purge: records should move through Keep → Refresh → Re-engage → Suppress → Archive → Delete, based on interaction, consent, retention rules and future value.
- Inconsistency breaks automation: “Buyer”, “buyer” and “BUYER” mean the same thing to a person but become three different segments to a campaign or workflow.
- Enrichment and lead scoring both decay: refresh high-value records more often, and recalibrate scores against actual outcomes so old activity stops inflating them.
- Clean records don’t prove anything happened: a mature programme verifies that the email sent, the handoff was accepted, and the booking arrived. Automation can execute a wrong decision faster and at scale.
At a Glance: Five Practices That Stop Bad CRM Data Costing Revenue
| Practice | What goes wrong without it | Practical control |
|---|---|---|
| Retire old data responsibly | Inflated pipeline, unreliable forecasts, wasted review time | Lifecycle rules: flag at 30 days with no activity, re-engage at 90, then suppress or archive |
| Clean and standardise | Wrong campaigns, duplicate messages, misrouted leads | Picklists, validation rules, duplicate detection at entry |
| Enrich continuously | Stale titles and employers, broken personalisation and routing | Refresh high-value accounts more often; track source and freshness |
| Define “good data” | Marketing, sales and finance report different numbers | Measurable rules across completeness, accuracy, consistency, freshness, permission and actionability |
| Recalibrate lead scoring | Sales chases false positives; trust between teams erodes | Compare scores with outcomes; decay old engagement; separate fit from intent |
1. Retire old data responsibly
Old data is not automatically bad data. A previous customer may become relevant again, while an inactive lead may still have historical or analytical value.
The objective should not be to delete everything after an arbitrary period. Every record should instead move through a defined lifecycle:
Keep → Refresh → Re-engage → Suppress → Archive → Delete
A company should establish rules based on factors such as:
- Time since the last meaningful interaction
- Contact and account status
- Opportunity stage
- Consent and communication preferences
- Legal or contractual retention requirements
- Historical and analytical value
- Probability of future engagement
For example, an opportunity marked “active” without an interaction or next step for 30 days could be flagged for review. After 90 days, it might move into a re-engagement programme. If the contact does not respond, the record could be suppressed or archived according to the company’s retention policy.
The cost of doing nothing
Stale records inflate the apparent size of the pipeline and make revenue forecasts unreliable. Sales representatives waste time reviewing inactive opportunities, while marketing teams continue paying to store or contact people who are unlikely to respond.
A simple way to estimate the productivity cost is:
Stale records × average review time × employee cost per hour
That calculation still excludes the larger cost of decisions made using an overstated pipeline.
2. Clean and standardise the data
CRM cleansing is more than removing duplicate contacts. It involves making records consistent enough to support reporting, segmentation, routing and automation.
Common problems include:
- Duplicate contacts and accounts
- Invalid email addresses and telephone numbers
- Missing lead sources or record owners
- Inconsistent countries, industries and job titles
- Free-text values where controlled options are needed
- Different versions of the same tag
- Opportunities without next actions
- Conflicting information across connected systems
A tag such as “Buyer” may also exist as “buyer,” “BUYER” and “Buyers.” A person reading the record will understand that these values mean roughly the same thing. A campaign, dashboard or workflow may treat them as entirely different segments. It is one of the six problems I keep finding in CRM audits, and rarely the most expensive.
Practical controls include:
- Approved picklists and naming conventions
- Validation rules for critical fields
- Duplicate detection at the point of entry
- Standard formats for telephone numbers and addresses
- Mandatory ownership and next-action fields
- Scheduled exception reports
- Named owners for correcting data-quality issues
The cost of doing nothing
Inconsistent data causes contacts to enter the wrong campaign, duplicate messages to reach the same customer and leads to be assigned to the wrong team. Reports become difficult to trust, so employees create separate spreadsheets and unofficial workarounds.
Eventually, the organisation pays twice: once for the CRM and again for the manual effort needed to compensate for its unreliable data.
3. Treat data enrichment as a continuous process
Data enrichment is frequently approached as a migration or implementation activity. Records are enhanced once, uploaded into the CRM and assumed to remain accurate.
But customer and company information constantly changes. People change roles. Companies merge, relocate or close. Telephone numbers become invalid. Account priorities shift. Previously complete records gradually become incomplete or misleading.
Enrichment should operate as a recurring process:
- Refresh high-value accounts more frequently
- Revalidate contacts before major campaigns
- Update job roles and company associations
- Track when and where each attribute was obtained
- Assign confidence and freshness indicators
- Prioritise fields that influence segmentation or decisions
- Avoid overwriting verified first-party data with weaker sources
Not every field requires the same refresh cycle. A contact’s name may remain stable for years, while employment details or buying intent can change within months.
The cost of doing nothing
Outdated enrichment damages personalisation. A message addressed to someone using an old title or employer immediately signals that the company does not know its customer. Better tools do not fix this. As I’ve argued before, AI didn’t solve the personalisation problem; it exposed it.
Salespeople also lose time researching information that the CRM was expected to provide. Lead routing, account prioritisation and territory planning become less reliable because they depend on obsolete attributes.
4. Define what “good data” means for your company
There is no universal definition of a perfect CRM record.
A property business, subscription company and B2B manufacturer will require different fields, update cycles and standards. Data that is essential for one team may have no operational value for another.
Every organisation should define its own data-quality rules across six dimensions:
- Completeness: Are the required fields populated?
- Accuracy: Does the information reflect reality?
- Consistency: Is the same information represented uniformly?
- Freshness: Was it validated recently enough?
- Permission: Can the data be used for the intended purpose?
- Actionability: Does the record contain an owner and a clear next step?
These standards should be converted into measurable rules. For example:
- Every active opportunity must have an owner.
- Every open opportunity must have a dated next action.
- Every marketable contact must have a recorded consent status and source.
- Every account classified as strategic must be reviewed within a defined period.
- Every closed opportunity must include a standardised reason.
The rules should also identify who owns the problem. Without ownership, data quality becomes everybody’s concern but nobody’s responsibility.
The cost of doing nothing
When “good data” is undefined, different teams create their own interpretations. Marketing counts one number of qualified leads, sales reports another and finance trusts neither.
This leads to conflicting dashboards, inconsistent customer treatment and slower decision-making. It also reduces the value of automation and AI because those systems scale the organisation’s underlying ambiguity. It is a big part of why so much of the AI personalisation opportunity still sits on a broken data foundation.
5. Recalibrate lead scoring regularly
Lead scoring is another activity often completed once and left untouched.
A score may initially reflect useful signals such as customer profile, engagement and buying behaviour. Over time, however, markets change, campaigns attract different audiences and customer behaviour evolves. Signals that once predicted conversion may become irrelevant.
A reliable scoring programme should regularly compare predicted quality with actual outcomes.
Review questions should include:
- Are highly scored leads converting?
- Which signals are common among won opportunities?
- Are some attributes being weighted too heavily?
- Are old activities continuing to increase scores?
- Are negative signals and inactivity included?
- Are different products or segments being judged by the same model?
- Does the sales team understand and trust the score?
Scores should decay when engagement becomes old. The model should also distinguish between profile fit and current intent: an ideal customer who is not ready to buy is not the same as an actively interested prospect with poor fit.
The cost of doing nothing
An outdated model directs salespeople toward false positives while genuine opportunities remain unattended. Marketing may appear to generate qualified leads, but sales sees little connection between the score and the likelihood of conversion.
The result is wasted capacity and declining trust between teams.
Go beyond clean records: verify execution
A clean CRM record does not prove that the intended action happened.
An automation may show that an email workflow was triggered even though the message failed. A handoff may appear complete while no salesperson accepted it. A booking request may have been created without reaching the scheduling system. Silent failures like these are among the most common reasons marketing automation stops working.
A mature CRM-hygiene programme should connect:
- The source data used to make the decision
- The action the workflow proposed
- The result produced by the downstream system
- Any mismatch or missing evidence
- The person responsible for resolving the exception
This is particularly important as companies introduce more automation and AI. Automation does not correct poor data by itself. It can execute the wrong decision faster and across a much larger audience.
The real cost of bad CRM data
The cost does not sit within a single department. It appears as:
- Wasted sales and marketing capacity
- Overstated pipelines and unreliable forecasts
- Lower email deliverability and campaign performance
- Missed follow-ups and lost revenue
- Poor customer experiences
- Unnecessary technology and data-storage costs
- Weak automation and AI outputs
- Compliance and reputational exposure
- Time spent manually reconciling reports
Organisations can start quantifying the impact using a few practical measures:
- Percentage of active leads with no activity in 30, 60 or 90 days
- Percentage of opportunities without an owner or next action
- Duplicate rate across contacts and accounts
- Percentage of marketable contacts with verifiable consent
- Percentage of emails, bookings and handoffs successfully completed
- Revenue value attached to stale opportunities
- Hours spent each month correcting or researching CRM data
- Conversion rates by lead-score band
Clean CRM data is an operating model
Buying another CRM will not solve a process, ownership or governance problem.
Healthy CRM data requires continuous retirement, cleansing, enrichment, validation and scoring. It also requires clear standards, accountable owners and evidence that downstream actions were completed.
The goal is not to build a CRM containing the largest possible number of records. The goal is to maintain information that is current, consistent, permissioned, prioritised and ready to support the next decision.
Before investing in more leads, more automation or another AI tool, organisations should first ask a simpler question:
Can we trust the data—and can we prove that the action it triggered actually happened?
Frequently Asked Questions
More than the hours spent fixing it. Stale records overstate the pipeline and make forecasts unreliable. Inconsistent fields send contacts into the wrong campaigns and leads to the wrong salespeople. Outdated enrichment breaks personalisation, and automation and AI act on the bad data faster and at scale. For the time cost alone, start with stale records × average review time × employee cost per hour.
Not automatically. Old data is not the same as bad data: a past customer may become relevant again, and inactive leads can still have analytical value. Move each record through a defined lifecycle (keep, refresh, re-engage, suppress, archive, delete) based on activity, consent, retention requirements and the likelihood of future engagement.
Flag every “active” opportunity with no logged interaction or next step in 30 days. Then track the share of active leads with no activity at 30, 60 and 90 days, and the revenue value attached to them. If a meaningful slice of your forecast sits in that group, the pipeline is smaller than it looks.
There is no universal standard. Each company should define it across six dimensions: completeness, accuracy, consistency, freshness, permission and actionability. Then turn those into measurable rules, such as every open opportunity having an owner and a dated next action, and give someone clear ownership of fixing issues.
Start with productivity: stale records × average review time × employee cost per hour. Then track the percentage of leads with no activity in 30, 60 or 90 days, the duplicate rate, contacts with verifiable consent, handoffs successfully completed, revenue attached to stale opportunities, and conversion rates by lead-score band.
No. Buying another CRM does not solve a process, ownership or governance problem, and automation does not correct poor data by itself. It can execute the wrong decision faster and across a larger audience. Fix the data and the operating model first, then add tools.
Is Your CRM Helping—or Holding You Back?
If your CRM contains stale leads, duplicate records, inconsistent fields or unreliable scoring, adding more automation will only multiply the problem.
I help businesses improve CRM performance through data audits, cleansing, enrichment, governance, lead-scoring optimisation and practical data-hygiene processes. The goal is simple: make your CRM data accurate, actionable and reliable enough to support sales, marketing and customer engagement.
If you need help evaluating or improving your CRM and customer data, reach out to me at harish@psharish.com or connect with me here.
Let’s turn your CRM from a database of records into a dependable engine for growth.
By PS Harish
25 July 2026Comments
No comments yet.
Leave A Comment